Best Qwen3.8 27B quant for your GPU
4 quantized files of Qwen/Qwen3.8-27B (27.32B): accuracy, tool calls and speed (no KLD: reference too large).
Qwen/Qwen3.8-27B (Apache-2.0). Dense 27B with the Qwen3.5 hybrid design: 64 layers, 16 full attention + 48 linear attention, 4 KV heads x 256, so the KV cache is small. Text-only GGUF quants from unsloth (vision projector not included). Tool calls and accuracy tested with thinking disabled.
Accuracy and speed only, no KLD: reference too large. The BF16 reference (about 55 GB) does not fit in our 32 GB test Mac (minipro), so there is no KLD for this model; we measured accuracy, tool calls and speed only. We never estimate KLD; picks for this model are ranked by measured accuracy (GSM8K + MMLU + ARC-C, 500 items, 95% CI) with tool calls as tie-break.
Charts
Every dot and bar is a measured file (GGUF). Hover or tap one for its numbers; each chart has a table under "Show the numbers". Download a PNG to share.
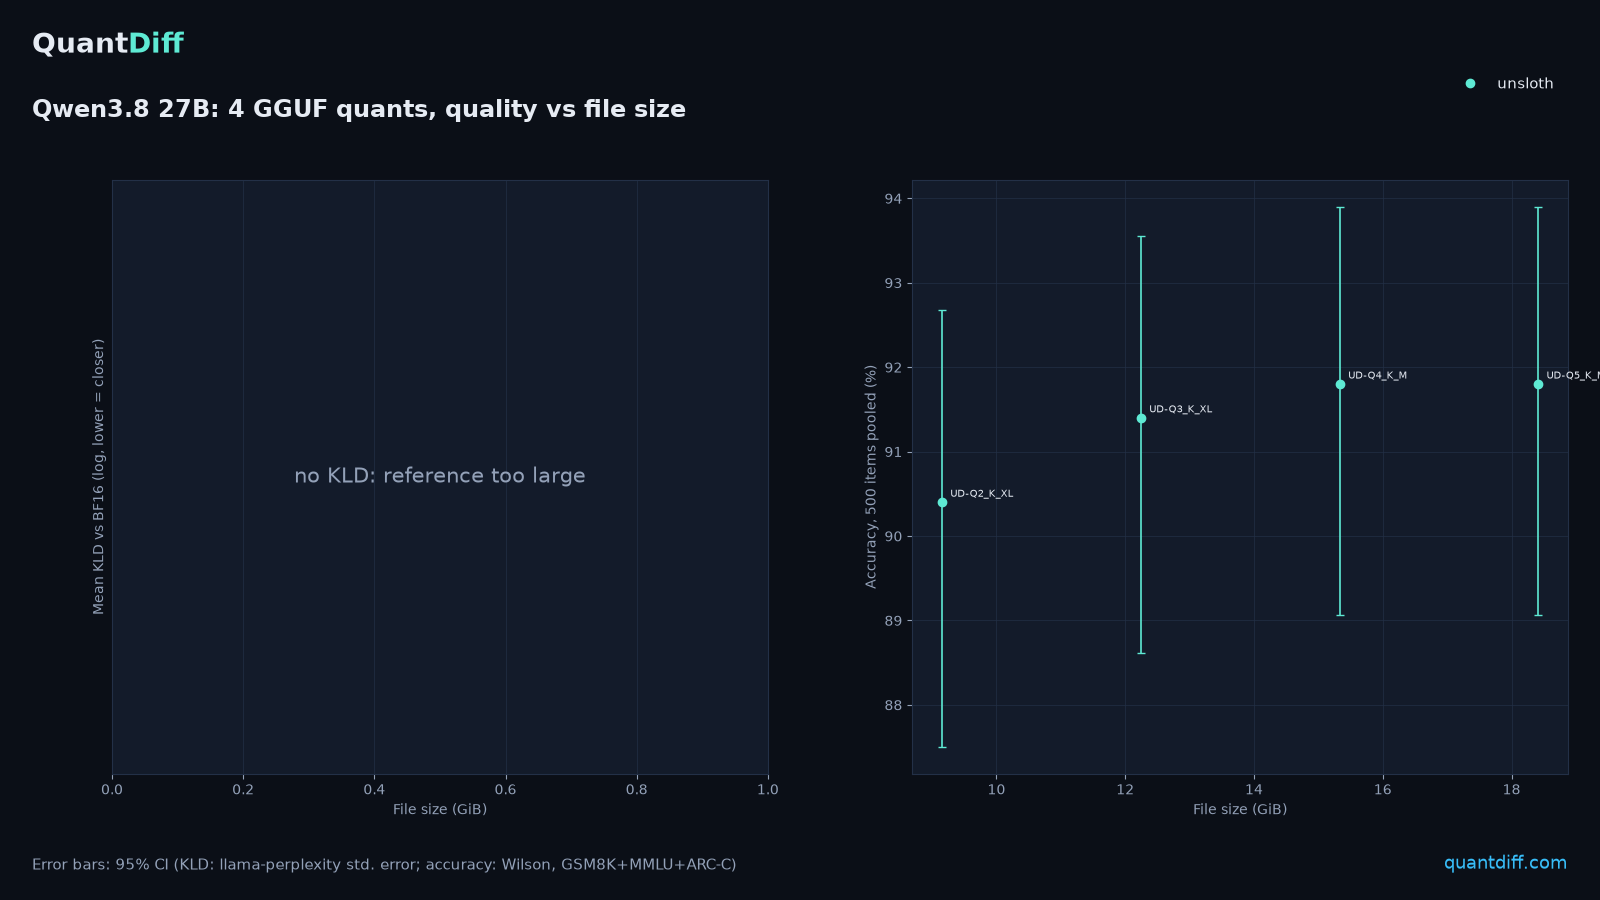
Qwen3.8 27B: accuracy vs file size
If a dot's bar reaches the shaded band, that file scores the same as the best one within the margin of error on our accuracy questions (GSM8K + MMLU + ARC-C); the smallest such file here is UD-Q2_K_XL at 9.15 GB.
- unsloth
- best file's 95% range
- clearly below the best
- our pick for 8 / 12 / 16 GB GPUs
Up: in %, bars = · Across: file size in GB (GiB) · = overlaps the band
Show the numbers (table)
| Quant | GB | Accuracy % | 95% interval | Correct | Tied with best | Pick |
|---|---|---|---|---|---|---|
| UD-Q2_K_XL | 9.15 | 90.4 | 87.5–92.7 | 452/500 | yes | 12 GB pick |
| UD-Q3_K_XL | 12.24 | 91.4 | 88.6–93.6 | 457/500 | yes | 16 GB pick |
| UD-Q4_K_M | 15.33 | 91.8 | 89.1–93.9 | 459/500 | yes | 24 GB pick |
| UD-Q5_K_M | 18.41 | 91.8 | 89.1–93.9 | 459/500 | yes |
Qwen3.8 27B: tool calls vs file size
If a dot's bar reaches the shaded band, that file scores the same as the best one within the margin of error on our tool-call tests; the smallest such file here is UD-Q2_K_XL at 9.15 GB.
- unsloth
- best file's 95% range
- clearly below the best
- our pick for 8 / 12 / 16 GB GPUs
Up: in %, bars = · Across: file size in GB (GiB) · = overlaps the band
Show the numbers (table)
| Quant | GB | Tool calls % | 95% interval | Correct | Tied with best | Pick |
|---|---|---|---|---|---|---|
| UD-Q2_K_XL | 9.15 | 87.5 | 82.2–91.4 | 175/200 | yes | 12 GB pick |
| UD-Q3_K_XL | 12.24 | 87.5 | 82.2–91.4 | 175/200 | yes | 16 GB pick |
| UD-Q4_K_M | 15.33 | 88.5 | 83.3–92.2 | 177/200 | yes | 24 GB pick |
| UD-Q5_K_M | 18.41 | 86.5 | 81.1–90.6 | 173/200 | yes |
Qwen3.8 27B: diff from the original (KLD)
No KLD for this model: The BF16 reference (about 55 GB) does not fit in our 32 GB test Mac (minipro), so there is no KLD for this model; we measured accuracy, tool calls and speed only.
Qwen3.8 27B: generation speed by quant and machine
Longer bar = faster replies. Smaller files are usually faster; the fastest measured here is UD-Q2_K_XL (unsloth) at 48 tok/s on RTX 5070 12GB (llama.cpp). Compare bars of the same colour only: each colour is a different machine.
- RTX 5070 12GB (llama.cpp)
- Apple M2 Pro 32GB (llama.cpp)
Across: (tokens per second)
Show the numbers (table)
| File | Publisher | GB | Machine | tok/s | Placement |
|---|---|---|---|---|---|
| UD-Q5_K_M | unsloth | 18.41 | Apple M2 Pro 32GB (llama.cpp) | 7.6 | full GPU |
| UD-Q4_K_M | unsloth | 15.33 | Apple M2 Pro 32GB (llama.cpp) | 8.8 | full GPU |
| UD-Q3_K_XL | unsloth | 12.24 | Apple M2 Pro 32GB (llama.cpp) | 9.4 | full GPU |
| UD-Q2_K_XL | unsloth | 9.15 | RTX 5070 12GB (llama.cpp) | 48.1 | full GPU |
| UD-Q2_K_XL | unsloth | 9.15 | Apple M2 Pro 32GB (llama.cpp) | 9.7 | full GPU |
Not sure which fits? Use the quant picker →
Recommendation by VRAM
"Best" = highest measured accuracy (500 items pooled) among files that fit fully on the GPU (file + 8192-token KV cache), tool-call score as tie-breaker. No KLD for this model (reference too large).
8GB GPU
Nothing we've tested fits fully in 8GB at 8192 context. Try a smaller model, run it GPU+RAM split, or rent a bigger GPU.
12GB GPU
- File size
- 9.15 GB
- no KLD: reference too large
- Accuracy (500 items)
- 90.4% (87.5–92.7)
- 87.5%
- Accuracy
- Generation ()
- 10 t/s on Apple M2 Pro 32GB full GPU
How to run this file
From unsloth/Qwen3.8-27B-GGUF, file Qwen3.8-27B-UD-Q2_K_XL.gguf.
(downloads it, then starts a chat; type /bye to quit):
ollama run hf.co/unsloth/Qwen3.8-27B-GGUF:Qwen3.8-27B-UD-Q2_K_XL.gguf: open the Discover tab, search unsloth/Qwen3.8-27B-GGUF, pick the UD-Q2_K_XL download, then load it from the Chat tab.
16GB GPU
- File size
- 12.24 GB
- no KLD: reference too large
- Accuracy (500 items)
- 91.4% (88.6–93.6)
- 87.5%
- Accuracy
- Generation ()
- 9 t/s on Apple M2 Pro 32GB full GPU
How to run this file
From unsloth/Qwen3.8-27B-GGUF, file Qwen3.8-27B-UD-Q3_K_XL.gguf.
(downloads it, then starts a chat; type /bye to quit):
ollama run hf.co/unsloth/Qwen3.8-27B-GGUF:Qwen3.8-27B-UD-Q3_K_XL.gguf: open the Discover tab, search unsloth/Qwen3.8-27B-GGUF, pick the UD-Q3_K_XL download, then load it from the Chat tab.
Fastest that fits: UD-Q2_K_XL (unsloth, 10 t/s, acc 90.4%, no KLD)
All Qwen3.8 27B quants
| Quant | Publisher | Size | Fits | mean | Gen | Run | ||
|---|---|---|---|---|---|---|---|---|
| UD-Q2_K_XL | unsloth imatrix | 9.15 GB | 12GB+ | n/a | — | 87.5% | 10 Apple M2 Pro 32GB 48 on RTX 5070 12GB |
settings & logs |
| UD-Q3_K_XL | unsloth imatrix | 12.24 GB | 16GB+ | n/a | — | 87.5% | 9 Apple M2 Pro 32GB | settings & logs |
| UD-Q4_K_M | unsloth imatrix | 15.33 GB | 24GB+ | n/a | — | 88.5% | 9 Apple M2 Pro 32GB | settings & logs |
| UD-Q5_K_M | unsloth imatrix | 18.41 GB | 24GB+ | n/a | — | 86.5% | 8 Apple M2 Pro 32GB | settings & logs |
Accuracy cells: % correct, with the 95% confidence interval (Wilson) underneath. ≈ = statistically tied with the best quant of the same model (intervals overlap). ▼ below = clearly worse than that model's best quant (intervals do not overlap). Ties are not ranked: sorting by an accuracy column puts tied quants together and orders them by KLD. How accuracy is measured.
GB = GiB (1024³ bytes). Measured on: tool calls: minipro (Apple M2 Pro 32GB); speed: RTX 5070 12GB, minipro (Apple M2 Pro 32GB); accuracy: minipro (Metal, Apple M2 Pro (Mac mini), 32 GB unified memory). On a different GPU, expect generation speed to scale roughly with memory bandwidth. Task accuracy (GSM8K / MMLU / ARC-C, % correct on fixed subsets of 150 / 200 / 150 items, frozen suite quantdiff-lmeval-v1) was measured with the same GGUF files and llama.cpp build on Ghost (CUDA, NVIDIA GeForce RTX 5070 12 GB (64 GB RAM)), minipro (Metal, Apple M2 Pro (Mac mini), 12-core CPU, 19-core GPU, 32 GB unified memory), minipro (Metal, Apple M2 Pro (Mac mini), 32 GB unified memory). Accuracy depends on the weights, not on the GPU, but small numeric differences between backends can flip individual answers. With these sample sizes, differences under about 5 points are within noise (± shown on run pages). Methodology.
GPU too small? Rent one.
Run a 32B model at Q6/Q8, or a 70B, on a cloud GPU for an hour or two instead of buying hardware.
Cloud GPU pods with 24-80GB cards (RTX 4090 / 5090 / A100 / H100) for big quants or BF16 reference runs.
Rent on RunPodGPU marketplace for renting a 24-48GB card for an evening of testing.
Rent on Vast.aiReferral links: QuantDiff may earn credit if you sign up. Referral partners have no say in scores or rankings.